3. 数据并行训练
任务目标
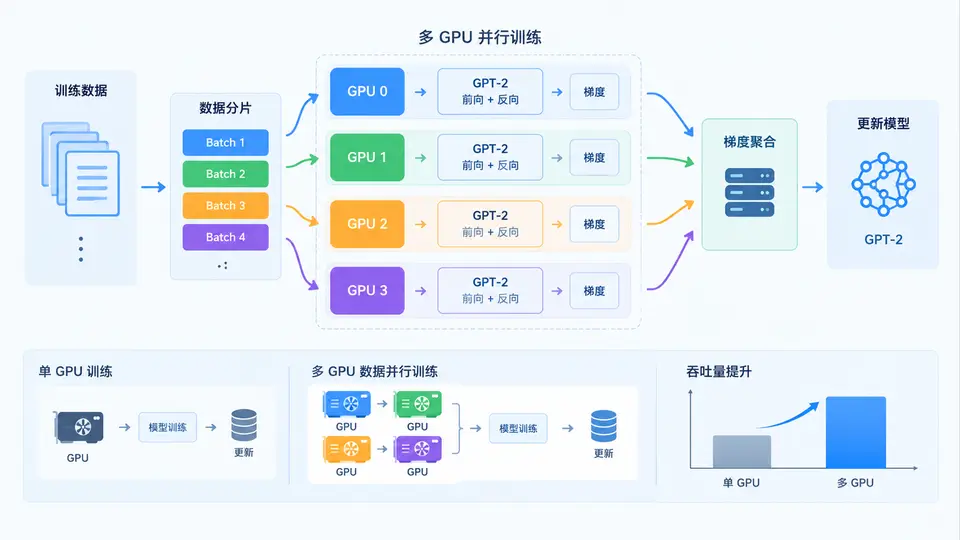
本案例使用 Megatron-LM 框架,在 2 张 GPU 上以数据并行方式训练 小规模模型(12 层,隐藏维度 768),对比单卡与双卡训练吞吐量(每秒处理的样本数),验证数据并行扩展性。
环境与依赖
- NVIDIA GPU ×2(显存 ≥16GB),CUDA 11.8+,PyTorch 2.0+
- Megatron-LM 源码(
git clone https://github.com/NVIDIA/Megatron-LM.git) - 依赖:
pip install transformers sentencepiece nltk
关键实现
数据并行在 Megatron-LM 中通过 --DDP-impl local 与 --tensor-model-parallel-size 1 启用(即纯数据并行)。核心训练入口复用框架的 pretrain_,无需修改源码。以下为最小可复现的训练启动脚本:
# 单卡基线(GPU 0)
python Megatron-LM/pretrain_ \
  --num-layers 12 --hidden-size 768 --num-attention-heads 12 \
  --seq-length 512 --max-position-embeddings 512 \
  --micro-batch-size 4 --global-batch-size 16 \
  --rampup-batch-size 4-16-1000 \
  --train-iters 200 --log-interval 10 \
  --data-path /data/wikitext/wikitext-2-v1_tokenized \
  --tokenizer-type GPT2BPETokenizer \
  --vocab-file /data/-vocab.json \
  --merge-file /data/-merges.txt \
  --split 98,2,0 \
  --optimizer adam --lr 1e-4 --weight-decay 0.1 \
  --lr-decay-style cosine --lr-warmup-iters 50 \
  --clip-grad 1.0 --init-method-std 0.02 \
  --attention-dropout 0.1 --hidden-dropout 0.1 \
  --tensor-model-parallel-size 1 --pipeline-model-parallel-size 1 \
  --DDP-impl local --use-checkpoint-opt_param-sync \
  --fp16 --seed 42 \
  --save /checkpoints/_single --save-interval 100 \
  --log-throughput

# 双卡数据并行(GPU 0,1)
python Megatron-LM/pretrain_ \
  --num-layers 12 --hidden-size 768 --num-attention-heads 12 \
  --seq-length 512 --max-position-embeddings 512 \
  --micro-batch-size 4 --global-batch-size 16 \
  --rampup-batch-size 4-16-1000 \
  --train-iters 200 --log-interval 10 \
  --data-path /data/wikitext/wikitext-2-v1_tokenized \
  --tokenizer-type GPT2BPETokenizer \
  --vocab-file /data/-vocab.json \
  --merge-file /data/-merges.txt \
  --split 98,2,0 \
  --optimizer adam --lr 1e-4 --weight-decay 0.1 \
  --lr-decay-style cosine --lr-warmup-iters 50 \
  --clip-grad 1.0 --init-method-std 0.02 \
  --attention-dropout 0.1 --hidden-dropout 0.1 \
  --tensor-model-parallel-size 1 --pipeline-model-parallel-size 1 \
  --DDP-impl local --use-checkpoint-opt_param-sync \
  --fp16 --seed 42 \
  --save /checkpoints/_ddp --save-interval 100 \
  --log-throughput \
  --distributed-backend nccl \
  --nproc-per-node 2
数据并行核心机制由框架自动处理:每张卡持有完整模型副本,前向/反向独立计算,梯度通过 torch.distributed 的 all-reduce 同步。关键参数说明:
--DDP-impl local:使用本地数据并行实现(非混合并行)--tensor-model-parallel-size 1:关闭张量并行,确保纯数据并行--global-batch-size 16:两卡各处理 8 样本/step,等效单卡 batch 翻倍--log-throughput:输出吞吐量日志
数据准备
使用 WikiText-2 数据集,需先 tokenize 为 Megatron 格式:
cd Megatron-LM
python tools/preprocess_data.py \
  --input /data/wikitext/wiki.train.tokens \
  --output-prefix /data/wikitext/wikitext-2-v1_tokenized \
  --vocab-file /data/-vocab.json \
  --merge-file /data/-merges.txt \
  --tokenizer-type GPT2BPETokenizer \
  --append-eod --workers 8
运行与验证
- 启动单卡训练,记录日志中
throughput字段(样本/秒) - 启动双卡训练(使用
torchrun --nproc_per_node=2或 mpirun),同样记录吞吐量 - 对比两个日志中的吞吐量数值
通过条件:双卡吞吐量显著高于单卡(理想情况接近 2 倍,实际受通信开销影响通常为 1.6~1.9 倍),且训练 loss 正常下降(约 200 iter 后 loss < 5.0)。若吞吐量无提升,检查 nvidia-smi 确认两张卡利用率均 >80%,并确认 NCCL 通信正常(日志无 all-reduce 超时错误)。
常见问题
- OOM 错误:降低
--micro-batch-size至 2 或 1 - 通信初始化失败:确认
MASTER_ADDR/MASTER_PORT环境变量已设置(torchrun 自动处理) - 吞吐量不升反降:检查是否误开张量并行(
--tensor-model-parallel-size必须为 1),或 GPU 间 PCIe/NVLink 带宽不足