3. 基于Rouge-L的摘要评测
任务目标
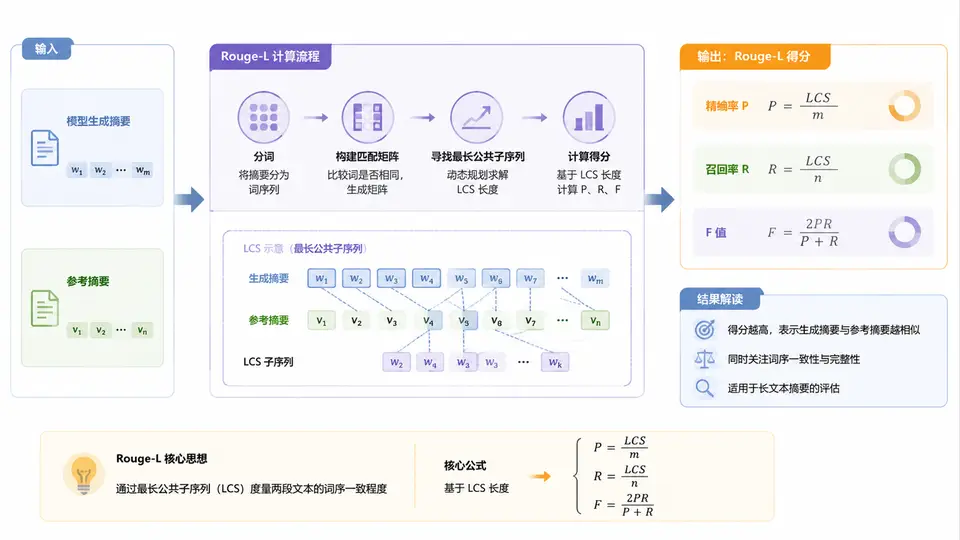
使用Rouge-L指标评估模型生成的摘要与参考摘要之间的相似度。Rouge-L基于最长公共子序列(LCS),同时考虑召回率(生成摘要覆盖参考摘要的程度)与精确率(生成摘要中与参考摘要匹配的比例),最终通过F1分数综合衡量。
环境与依赖
需要Python 3.8+,并安装以下库:
pip install rouge-score核心实现
以下代码完成Rouge-L的完整计算流程:
from rouge_score import rouge_scorer

def evaluate_rouge_l(reference: str, generated: str) -> dict:
    """
    计算单条样本的Rouge-L分数。
    返回包含 recall, precision, fmeasure 的字典。
    """
    scorer = rouge_scorer.RougeScorer(['rougeL'], use_stemmer=False)
    scores = scorer.score(reference, generated)
    return {
        'recall': scores['rougeL'].recall,
        'precision': scores['rougeL'].precision,
        'fmeasure': scores['rougeL'].fmeasure
    }

# 最小可运行示例
if __name__ == '__main__':
    ref = "The cat sat on the mat and looked at the dog."
    gen = "The cat sat on the mat."
    result = evaluate_rouge_l(ref, gen)
    print(f"Rouge-L Recall:    {result['recall']:.4f}")
    print(f"Rouge-L Precision: {result['precision']:.4f}")
    print(f"Rouge-L F1:        {result['fmeasure']:.4f}")
运行方式
- 将上述代码保存为
rouge_l_eval.py。 - 在终端执行:
python rouge_l_eval.py
验证方法与判定标准
运行后观察输出,预期结果(由代码逻辑直接推出):
- 生成摘要
"The cat sat on the mat."是参考摘要的前缀,LCS长度为6个词(the, cat, sat, on, the, mat),参考摘要共12个词,生成摘要共6个词。 - 因此 Recall = 6/12 = 0.5000,Precision = 6/6 = 1.0000,F1 = 2×0.5×1.0/(0.5+1.0) ≈ 0.6667。
通过条件:程序无报错,且输出的三个数值与上述预期一致(允许浮点显示误差±0.0001)。若需评估批量摘要,可循环调用 evaluate_rouge_l 并对各指标取均值。
常见问题
- 中文文本:默认按空格分词,中文需先使用jieba等工具分词后再传入,否则LCS按字符计算导致结果失真。
- 多参考摘要:rouge-score库支持传入多个参考,取最高分;本案例为单参考场景,如需扩展可参考官方文档。