3. RTL代码行数统计
任务说明
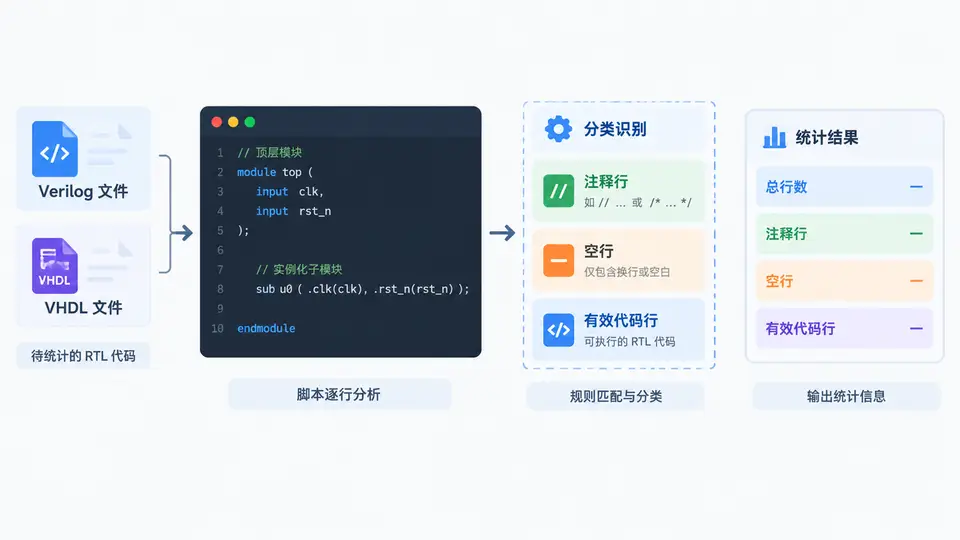
统计Verilog/VHDL源文件中的代码行数,将行分为三类:空行、注释行(含整行注释与块注释)和有效代码行。脚本需支持单个文件或目录批量统计,输出各类行数及占比。
实现思路
逐行扫描源文件,维护一个状态变量跟踪是否处于块注释(/* ... */)内部。对每一行依次判断:去除首尾空白后为空则计空行;若处于块注释中或该行整体为注释则计注释行;否则计有效代码行。块注释跨行时,起始行与结束行均计入注释行。
完整代码(Python 3)
#!/usr/bin/env python3
"""RTL代码行数统计工具:区分空行、注释行、有效代码行。"""
import os
import sys

def count_lines(filepath):
    """统计单个文件,返回 (总行数, 空行, 注释行, 有效代码行)。"""
    total = blank = comment = code = 0
    in_block_comment = False

    with open(filepath, 'r', encoding='utf-8', errors='ignore') as f:
        for raw_line in f:
            total += 1
            line = raw_line.strip()

            # 空行(含仅空白字符)
            if not line:
                blank += 1
                continue

            # 判断是否处于块注释中
            if in_block_comment:
                comment += 1
                if '*/' in line:
                    in_block_comment = False
                continue

            # 整行注释:// 开头,或 /* */ 在同一行内
            if line.startswith('//'):
                comment += 1
                continue

            if line.startswith('/*'):
                comment += 1
                if '*/' not in line:
                    in_block_comment = True
                continue

            # 行内代码后跟注释(如 "assign a = b; // comment")
            # 仍计为有效代码行,不做拆分
            code += 1

    return total, blank, comment, code

def main():
    if len(sys.argv) < 2:
        print("用法: python rtl_line_counter.py <文件或目录> [<文件或目录> ...]")
        sys.exit(1)

    targets = sys.argv[1:]
    files = []
    for t in targets:
        if os.path.isfile(t):
            files.append(t)
        elif os.path.isdir(t):
            for root, _, filenames in os.walk(t):
                for fn in filenames:
                    if fn.endswith(('.v', '.sv', '.vh', '.svh', '.vhd', '.vhdl')):
                        files.append(os.path.join(root, fn))
        else:
            print(f"警告: 路径不存在,跳过 {t}")

    if not files:
        print("未找到任何 .v/.sv/.vh/.svh/.vhd/.vhdl 文件")
        sys.exit(1)

    grand_total = grand_blank = grand_comment = grand_code = 0

    for fp in sorted(files):
        t, b, c, k = count_lines(fp)
        grand_total += t
        grand_blank += b
        grand_comment += c
        grand_code += k
        pct = (k / t * 100) if t else 0
        print(f"{fp}: 总行数={t}, 空行={b}, 注释={c}, 有效代码={k}, 有效占比={pct:.1f}%")

    print("-" * 60)
    gt = grand_total
    gp = (grand_code / gt * 100) if gt else 0
    print(f"合计: 总行数={gt}, 空行={grand_blank}, 注释={grand_comment}, "
          f"有效代码={grand_code}, 有效占比={gp:.1f}%")

if __name__ == '__main__':
    main()
运行方式
# 统计单个文件
python3 rtl_line_counter.py counter.v

# 统计目录下所有RTL文件(递归)
python3 rtl_line_counter.py ./rtl/

# 同时统计多个文件/目录
python3 rtl_line_counter.py top.v ./module_a/ ./module_b/
验证方法
用以下测试文件验证脚本正确性:
// file: test.v
module test;
  // 行注释
  reg a;
  /* 块注释开始
     跨行注释
     块注释结束 */
  wire b;
  assign b = a;  // 行尾注释(仍计有效代码)

  initial begin
    a = 1'b0;
  end
endmodule
预期输出(该文件共12行:空行1行、注释5行、有效代码6行):
test.v: 总行数=12, 空行=1, 注释=5, 有效代码=6, 有效占比=50.0%
通过条件:脚本输出与上述预期一致,且对含块注释跨行、行尾注释、连续空行的文件均能正确分类。
已知限制
本脚本不处理以下情况(对绝大多数RTL代码无影响):
1. 字符串中包含 // 或 /* 的边界情况;
2. 预处理指令(如 `ifdef)所在行计为有效代码行;
3. 行内代码后跟块注释起始(如 assign a = b; /* comment */)时,该行计为有效代码,后续跨行部分仍正确识别。