3. 文件单词统计
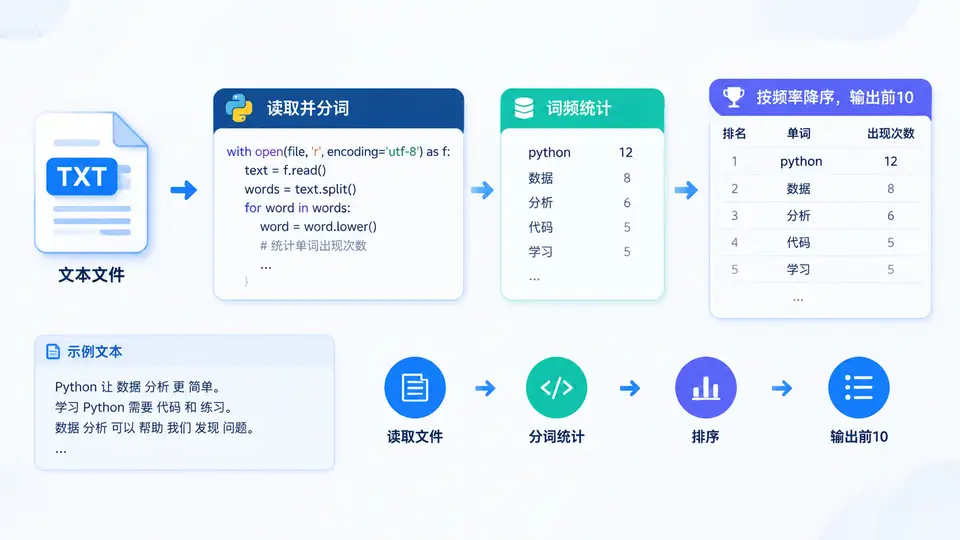
任务说明
读取一个文本文件,统计其中每个单词出现的次数,并按频率降序输出前10个单词。单词定义为由字母或数字组成的连续序列(不区分大小写),标点符号和空白字符作为分隔符。
实现代码
import re
from collections import Counter

def count_words(file_path, top_n=10):
    """统计文件中每个单词出现次数,返回频率最高的前top_n个单词列表。

    参数:
        file_path: 文本文件路径
        top_n: 返回前N个高频词,默认10

    返回:
        list of (word, count) 元组,按频率降序排列
    """
    try:
        with open(file_path, 'r', encoding='utf-8') as f:
            text = f.read()
    except FileNotFoundError:
        print(f"错误:文件 {file_path} 不存在")
        return []
    except Exception as e:
        print(f"读取文件失败:{e}")
        return []

    # 提取单词:字母或数字组成的连续序列,统一转为小写
    words = re.findall(r'[a-zA-Z0-9]+', text.lower())

    # 统计频率并按降序排列
    word_counts = Counter(words)
    top_words = word_counts.most_common(top_n)

    return top_words

# 示例使用
if __name__ == "__main__":
    # 创建示例文件(实际使用时替换为真实文件路径)
    sample_content = """Python is a powerful programming language.
    Python is easy to learn and Python is widely used.
    Data science and web development both use Python.
    """

    with open('sample.txt', 'w', encoding='utf-8') as f:
        f.write(sample_content)

    result = count_words('sample.txt', top_n=10)

    if result:
        print("频率最高的前10个单词:")
        for word, count in result:
            print(f"{word}: {count}")
    else:
        print("未统计到任何单词")
代码说明
代码使用正则表达式 [a-zA-Z0-9]+ 从文本中提取单词,统一转为小写后通过 Counter 统计频次,最后调用 most_common(top_n) 获取频率最高的前10个单词。文件读取包含异常处理,文件不存在或读取失败时会返回空列表并提示错误。
运行与验证
将上述代码保存为 word_count.py,在命令行执行:
python word_count.py程序会先创建包含示例文本的 sample.txt,然后统计并输出结果。预期输出为:
频率最高的前10个单词:
python: 4
is: 3
and: 2
a: 1
powerful: 1
programming: 1
language: 1
easy: 1
to: 1
learn: 1
验证判定标准:输出结果中 python 出现4次(示例文本中确实出现4次),其余单词频次与示例文本内容一致,且按频次降序排列。如需统计其他文件,将 count_words 的第一个参数替换为目标文件路径即可。