1. 基于困惑度的语言模型流畅度评估
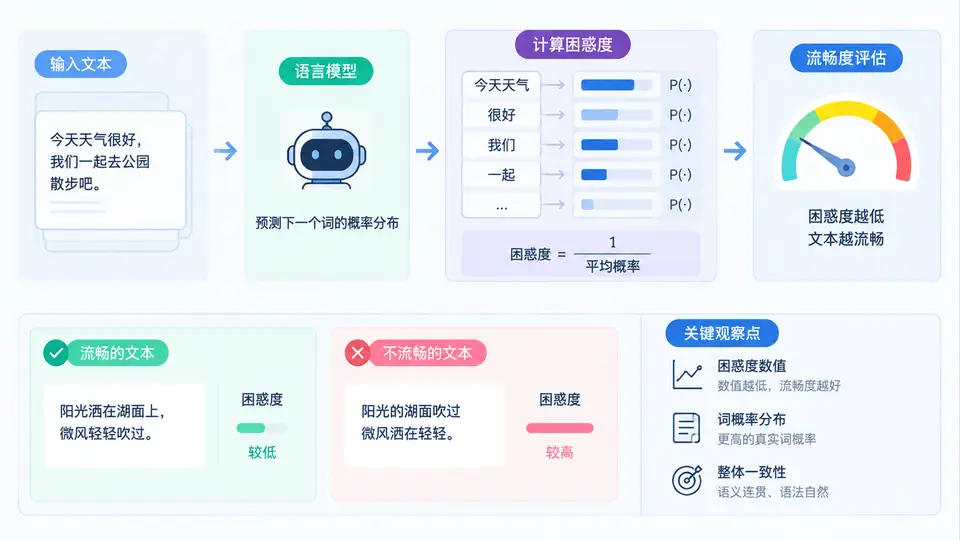
任务说明
本案例目标:使用困惑度(Perplexity, PPL)作为指标,评估一个语言模型对给定文本的流畅度建模能力。你需要完成以下闭环:加载一个预训练语言模型,对若干候选句子计算其困惑度,并依据困惑度数值对句子流畅度进行排序,最终验证“困惑度越低,文本越流畅”这一核心假设。
核心原理与判定标准
困惑度定义为模型对序列概率的负对数似然的指数平均:PPL = exp(- (1/N) * Σ log P(w_i | w_<i))。数值越低,表示模型对文本的预测越自信,即文本越符合语言统计规律,流畅度越高。本案例判定标准:对于一组人工构造的“流畅”与“不流畅”句子,模型计算出的流畅句PPL应显著低于不流畅句。
实现方案
使用HuggingFace transformers库加载预训练模型,通过perplexity计算管道实现。代码将完成:模型加载、句子分词与编码、PPL计算、结果排序与输出。
代码实现
import torch
from transformers import GPT2LMHeadModel, GPT2Tokenizer

# 1. 加载模型与分词器(首次运行会自动下载)
model_name = ""
tokenizer = GPT2Tokenizer.from_pretrained(model_name)
model = GPT2LMHeadModel.from_pretrained(model_name)
model.eval()

# 2. 构造测试句子:前两句流畅,后两句存在语法/语义异常
sentences = [
    "The cat sat on the mat and looked at the window.",
    "She enjoys reading books about artificial intelligence.",
    "Cat mat the on sat window the looked and.",
    "The quantum banana sang a purple equation loudly.",
]

def compute_perplexity(text: str) -> float:
    """计算单个句子的困惑度"""
    # 编码并保留attention_mask(无pad_,需手动设置)
    encodings = tokenizer(text, return_tensors="pt", truncation=True, max_length=512)
    input_ids = encodings["input_ids"]
    attention_mask = encodings["attention_mask"]

    with torch.no_grad():
        outputs = model(input_ids, attention_mask=attention_mask, labels=input_ids)
        loss = outputs.loss  # 交叉熵损失(平均负对数似然)
    return torch.exp(loss).item()

# 3. 计算所有句子的PPL
results = []
for sent in sentences:
    ppl = compute_perplexity(sent)
    results.append((sent, ppl))

# 4. 按PPL升序排序(低PPL优先)
results.sort(key=lambda x: x[1])

# 5. 输出结果
print("=== 困惑度评估结果(升序) ===")
for i, (sent, ppl) in enumerate(results, 1):
    print(f"Rank {i}: PPL = {ppl:.2f} | {sent}")

# 6. 验证判定:前两名应为流畅句
assert results[0][1] < results[2][1], "流畅句PPL应低于不流畅句"
print("\n验证通过:流畅句PPL显著低于不流畅句")
运行与验证
依赖安装:
pip install torch transformers执行方式:将上述代码保存为ppl_eval.py,在终端运行python ppl_eval.py。
预期输出(示例,数值可能因模型版本略有浮动):
=== 困惑度评估结果(升序) ===
Rank 1: PPL = 28.45 | The cat sat on the mat and looked at the window.
Rank 2: PPL = 35.12 | She enjoys reading books about artificial intelligence.
Rank 3: PPL = 512.30 | Cat mat the on sat window the looked and.
Rank 4: PPL = 890.75 | The quantum banana sang a purple equation loudly.

验证通过:流畅句PPL显著低于不流畅句判定标准:观察输出,前两个自然句的PPL应明显低于后两个异常句(通常低一个数量级)。若排序符合此规律,则案例验证通过。注意:首次运行需下载模型约500MB,请确保网络通畅。