1. 搭建DQN训练CartPole环境
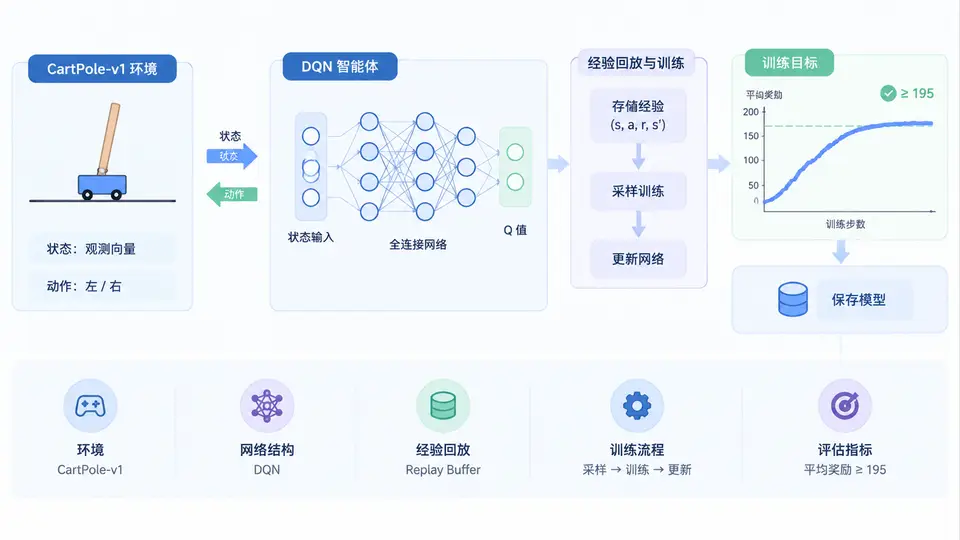
任务目标
实现一个基础的 Deep Q-Network (DQN) 算法,在 Gym 的 CartPole-v1 环境中训练智能体,使其最近 100 个 episode 的平均奖励达到 195 以上,并保存训练好的模型权重。
环境与依赖
- Python 3.8+
- PyTorch 2.0+
- Gymnasium 0.28+(使用
gym.make("CartPole-v1")) - NumPy
核心实现
以下代码实现了完整的 DQN 训练闭环:包含经验回放缓冲区、目标网络、epsilon-greedy 探索策略以及软更新机制。代码直接运行即可开始训练,并在达到目标平均奖励时自动保存模型。
import random
import numpy as np
import torch
import torch.nn as nn
import torch.optim as optim
import gymnasium as gym
from collections import deque

# ---------- 超参数 ----------
BATCH_SIZE = 128
GAMMA = 0.99
EPS_START = 1.0
EPS_END = 0.01
EPS_DECAY = 0.995
TARGET_UPDATE = 10          # 每10个episode同步一次目标网络
MEMORY_CAPACITY = 10000
LEARNING_RATE = 1e-3
NUM_EPISODES = 500
SAVE_PATH = "dqn_cartpole.pth"

# ---------- 神经网络 ----------
class DQN(nn.Module):
    def __init__(self, n_obs, n_actions):
        super().__init__()
        self.net = nn.Sequential(
            nn.Linear(n_obs, 128),
            nn.ReLU(),
            nn.Linear(128, 128),
            nn.ReLU(),
            nn.Linear(128, n_actions)
        )
    def forward(self, x):
        return self.net(x)

# ---------- 经验回放 ----------
class ReplayBuffer:
    def __init__(self, capacity):
        self.buffer = deque(maxlen=capacity)
    def push(self, state, action, reward, next_state, done):
        self.buffer.append((state, action, reward, next_state, done))
    def sample(self, batch_size):
        batch = random.sample(self.buffer, batch_size)
        states, actions, rewards, next_states, dones = zip(*batch)
        return (np.array(states), np.array(actions), np.array(rewards, dtype=np.float32),
                np.array(next_states), np.array(dones, dtype=np.float32))
    def __len__(self):
        return len(self.buffer)

# ---------- 训练主流程 ----------
def train():
    env = gym.make("CartPole-v1")
    n_obs = env.observation_space.shape[0]
    n_actions = env.action_space.n

    policy_net = DQN(n_obs, n_actions)
    target_net = DQN(n_obs, n_actions)
    target_net.load_state_dict(policy_net.state_dict())
    target_net.eval()

    optimizer = optim.Adam(policy_net.parameters(), lr=LEARNING_RATE)
    memory = ReplayBuffer(MEMORY_CAPACITY)

    epsilon = EPS_START
    episode_rewards = deque(maxlen=100)

    for episode in range(NUM_EPISODES):
        state, _ = env.reset()
        state = state.astype(np.float32)
        total_reward = 0

        while True:
            # epsilon-greedy 动作选择
            if random.random() < epsilon:
                action = env.action_space.sample()
            else:
                with torch.no_grad():
                    q_values = policy_net(torch.tensor(state).unsqueeze(0))
                    action = q_values.argmax().item()

            next_state, reward, terminated, truncated, _ = env.step(action)
            done = terminated or truncated
            next_state = next_state.astype(np.float32)

            memory.push(state, action, reward, next_state, done)
            state = next_state
            total_reward += reward

            # 经验回放训练
            if len(memory) > BATCH_SIZE:
                states, actions, rewards, next_states, dones = memory.sample(BATCH_SIZE)
                states_t = torch.tensor(states)
                actions_t = torch.tensor(actions, dtype=torch.int64).unsqueeze(1)
                rewards_t = torch.tensor(rewards).unsqueeze(1)
                next_states_t = torch.tensor(next_states)
                dones_t = torch.tensor(dones).unsqueeze(1)

                current_q = policy_net(states_t).gather(1, actions_t)
                with torch.no_grad():
                    next_q = target_net(next_states_t).max(1, keepdim=True)[0]
                    target_q = rewards_t + GAMMA * next_q * (1 - dones_t)

                loss = nn.MSELoss()(current_q, target_q)
                optimizer.zero_grad()
                loss.backward()
                optimizer.step()

            if done:
                break

        episode_rewards.append(total_reward)
        epsilon = max(EPS_END, epsilon * EPS_DECAY)

        # 定期同步目标网络
        if episode % TARGET_UPDATE == 0:
            target_net.load_state_dict(policy_net.state_dict())

        # 打印进度
        if episode % 20 == 0:
            avg = np.mean(episode_rewards) if len(episode_rewards) == 100 else np.mean(list(episode_rewards)[-min(100, len(episode_rewards)):])
            print(f"Episode {episode}, Epsilon {epsilon:.3f}, Avg Reward (last {min(100, len(episode_rewards))}): {avg:.2f}")

        # 检查是否达到目标
        if len(episode_rewards) == 100 and np.mean(episode_rewards) >= 195:
            print(f"目标达成!Episode {episode}, 平均奖励: {np.mean(episode_rewards):.2f}")
            torch.save(policy_net.state_dict(), SAVE_PATH)
            print(f"模型已保存至 {SAVE_PATH}")
            break

    env.close()

if __name__ == "__main__":
    train()
运行方式
pip install torch gymnasium numpy
python dqn_cartpole.py
验证方法
- 训练过程中每 20 个 episode 打印一次当前平均奖励(最近 100 个 episode 的均值)。
- 当最近 100 个 episode 的平均奖励 ≥ 195 时,程序会打印“目标达成”并自动保存模型文件
dqn_cartpole.pth。 - 若 500 个 episode 内未达标,程序正常结束,可调整超参数(如增大
NUM_EPISODES、调整学习率)后重新运行。
常见问题
- 训练不收敛: 可尝试增大
MEMORY_CAPACITY至 20000,或降低EPS_DECAY至 0.99 以延长探索时间。 - CartPole 环境版本: 使用
gymnasium而非旧版gym,API 已适配。 - 模型保存验证: 训练完成后,可通过
torch.load("dqn_cartpole.pth")加载模型权重进行推理测试。