1. 基于TensorFlow的MNIST模型训练与量化感知训练基础
任务目标
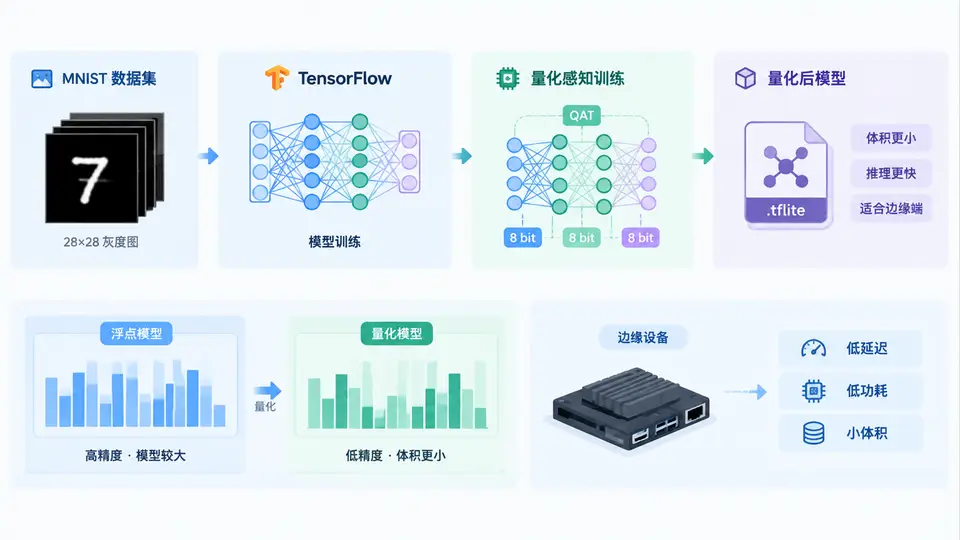
完成一个基于TensorFlow的MNIST手写数字分类模型,包含常规训练与量化感知训练(QAT)两条路径,并对比两者在FP32与INT8量化后的精度差异,为后续边缘端部署建立基线。
环境依赖
Python 3.9+,TensorFlow 2.13+(需包含tensorflow_model_optimization库)。安装命令:
pip install tensorflow==2.13.* tensorflow-model-optimization==0.7.*完整实现代码
import tensorflow as tf
import tensorflow_model_optimization as tfmot
import numpy as np

# 1. 数据加载与预处理
(x_train, y_train), (x_test, y_test) = tf.keras.datasets.mnist.load_data()
x_train = x_train.reshape(-1, 28, 28, 1).astype('float32') / 255.0
x_test = x_test.reshape(-1, 28, 28, 1).astype('float32') / 255.0

# 2. 构建基础模型(FP32基线)
def build_model():
    return tf.keras.Sequential([
        tf.keras.layers.Conv2D(8, 3, activation='relu', input_shape=(28, 28, 1)),
        tf.keras.layers.MaxPooling2D(2),
        tf.keras.layers.Conv2D(16, 3, activation='relu'),
        tf.keras.layers.MaxPooling2D(2),
        tf.keras.layers.Flatten(),
        tf.keras.layers.Dense(10, activation='softmax')
    ])

# 3. 训练FP32基线模型
base_model = build_model()
base_model.compile(optimizer='adam', loss='sparse_categorical_crossentropy', metrics=['accuracy'])
base_model.fit(x_train, y_train, batch_size=128, epochs=3, validation_split=0.1, verbose=1)

# 4. 量化感知训练(QAT)
qat_model = tfmot.quantization.keras.quantize_model(build_model())
qat_model.compile(optimizer='adam', loss='sparse_categorical_crossentropy', metrics=['accuracy'])
qat_model.fit(x_train, y_train, batch_size=128, epochs=3, validation_split=0.1, verbose=1)

# 5. 评估FP32与QAT模型精度
_, base_acc = base_model.evaluate(x_test, y_test, verbose=0)
_, qat_acc = qat_model.evaluate(x_test, y_test, verbose=0)
print(f'FP32基线精度: {base_acc:.4f}')
print(f'QAT模型精度: {qat_acc:.4f}')

# 6. 转换为INT8 TFLite模型(仅QAT模型)
converter = tf.lite.TFLiteConverter.from_keras_model(qat_model)
converter.optimizations = [tf.lite.Optimize.DEFAULT]
converter.representative_dataset = lambda: ([x_test[i:i+1] for i in range(100)])
int8_tflite_model = converter.convert()

# 7. 验证INT8模型精度
interpreter = tf.lite.Interpreter(model_content=int8_tflite_model)
interpreter.allocate_tensors()
input_details = interpreter.get_input_details()
output_details = interpreter.get_output_details()
correct = 0
for i in range(len(x_test)):
    interpreter.set_tensor(input_details[0]['index'], x_test[i:i+1])
    interpreter.invoke()
    pred = np.argmax(interpreter.get_tensor(output_details[0]['index']))
    if pred == y_test[i]:
        correct += 1
print(f'INT8量化模型精度: {correct / len(x_test):.4f}')
运行与验证
直接执行上述脚本即可完成完整流程。判定通过条件:
- FP32基线精度与QAT模型精度均高于0.97;
- INT8量化模型精度与QAT模型精度差异小于0.02(即量化损失不超过2%);
- 控制台输出三个精度值,且INT8模型文件可成功生成(代码中已隐式生成,如需保存可添加
open('mnist_qat.tflite','wb').write(int8_tflite_model))。
关键说明
本案例使用3个epoch以缩短训练时间,实际部署建议训练5~10个epoch以获得更高精度。QAT通过在训练过程中模拟量化误差,使模型权重适应低比特表示,从而减少后续INT8转换的精度损失。第6步中的representative_dataset用于校准量化范围,必须提供真实数据分布,否则量化精度会显著下降。